
Artificial Intelligence (AI) Chip Market Size, Key Companies, Company Market Share, Chip Production Volume, Wafer Capacity, Technology Adoption, Pricing Trends, Competitive Positioning, and Demand Analysis
Artificial Intelligence (AI) Chip Market (By Technology: Machine learning, Natural language processing, Context-aware computing, Computer vision, Predictive analysis; By Chip Type: GPU, ASIA, FPGA, CPU, Others; By Processing Type: Edge, Cloud; By Function: Training, Inference; By End-Users: Manufacturing, Healthcare, Automotive, Agriculture, Retail, Human Resources, Marketing, BFSI, Government, Others) - Global Industry Analysis, Size, Trends, Leading Companies, Regional Outlook, and Forecast 2026 to 2035
Source: https://www.precedenceresearch.com/artificial-intelligence-chip-market
 Get a Sample
 Table Of Content


What is the Artificial Intelligence (AI) Chip Market Size?
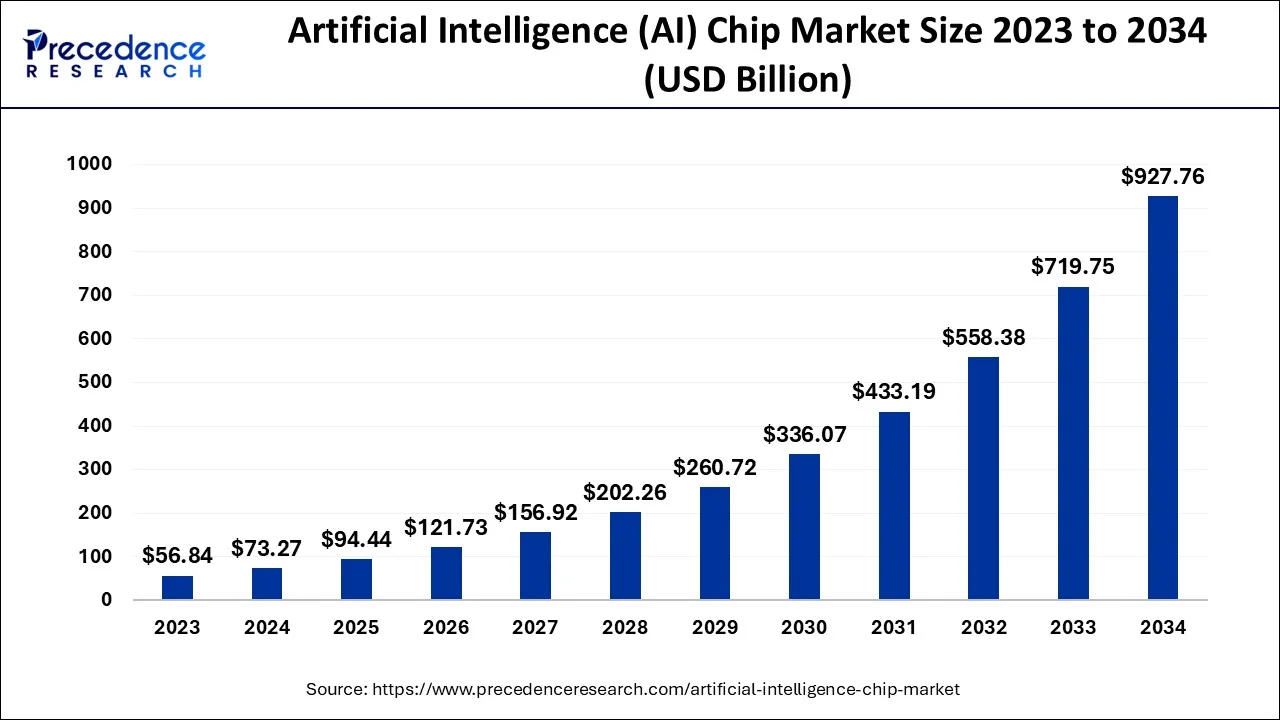
The global artificial intelligence (AI) chip market size is predicted to increase from USD 121.73 billion in 2026 to approximately USD 1,104.68 billion by 2035, representing a CAGR of 27.88% from 2026 to 2035. Increasing demand for deep learning and deployment of artificial intelligence (AI) in various industries are boosting the growth of the artificial intelligence chip market.
Key Takeaways
- AI chip demand is moving beyond GPU-only scaling as generative, agentic, and physical AI add new workloads.
- Data-center accelerators remain the largest value pool, while inference and edge chips grow across more applications.
- Performance per watt, memory bandwidth, interconnect, cost per token, and software compatibility now matter as much as raw speed.
- Supply is limited by advanced manufacturing, packaging, HBM, and testing capacity, not wafers alone.
- Inference is becoming a steady workload because agents, copilots, and real-time applications run all day.
- Pricing is judged by cost per inference, performance per dollar, and performance per watt rather than chip ASP alone.
- Hyperscalers still hold most data-center demand, though enterprise, sovereign AI, automotive, robotics, and edge are widening the base.
- High-end accelerators stay concentrated among a few vendors, but custom silicon is spreading competition.
- Software ecosystems, capital needs, and manufacturing access keep entry barriers high.
- By 2035, competition should center on inference economics, agentic workloads, power efficiency, custom silicon, and integrated platforms.
Overview
How AI Compute is Moving Beyond GPU-Only Scaling
The market is splitting in two. High-value data-center accelerators still dominate, backed by hyperscaler spending, foundation-model training, inference, and ever larger AI clusters. Meanwhile, NPUs and AI accelerators are moving into PCs, smartphones, vehicles, robots, and industrial systems.
The next stage of competition will turn less on raw FLOPS and more on performance per watt, memory bandwidth, interconnect, cost per token, software compatibility, utilization, and scalability. The contest is moving from single chips to complete platforms that bundle silicon, memory, networking, packaging, software, and rack design.
Key Coverage
- Data-center versus edge AI revenue pools
- Training versus inference economics
- GPU, ASIC, NPU, CPU, and heterogeneous architectures
- Regional demand and manufacturing exposure
- ASP, cost-per-token and performance-per-watt benchmarking
- AI accelerator capacity and advanced-node dependence
- Competitive share, product roadmaps, and strategic positioning
Segmentation Analysis
Data-Center Accelerators Lead on Value While Inference and Edge Grow Faster
Data-center accelerators remain the largest value pool, especially high-performance GPUs and custom accelerators in hyperscale and AI-cloud sites. The fastest structural growth, though, is in inference-optimized chips, as AI applications move from model training into continuous production use.
The segmentation covers GPU, ASIC, NPU, CPU, and FPGA acceleration, training versus inference, cloud versus on-premise, and data center versus edge. AI chips in smartphones, PCs, autonomous systems, robots, and industrial equipment are adding units at a growing rate, even though their ASPs sit far below frontier data-center accelerators.
Key Coverage
- Architecture share and CAGR
- Training versus inference
- Data-center versus edge
- Cloud versus enterprise
- Smartphone, PC, automotive, and industrial AI
- High-value versus high-volume chips
- Advanced-node versus mature-node demand
Market Dynamics
What is Changing AI Chip Economics as Inference Demand Grows?
Demand for AI compute keeps climbing, but its shape is changing. Training is still extremely compute-heavy, yet inference is becoming a steady workload because AI agents, copilots, autonomous systems, and real-time applications run around the clock.
Energy efficiency matters just as much. Large AI clusters need advanced cooling, high-bandwidth memory, and fast interconnects, so performance per watt and real compute utilization guide buying decisions. That favors specialized architectures over simply bigger general-purpose accelerators.
The analysis measures how model size, token generation, context length, inference frequency, utilization, power use, and cluster scaling affect chip demand.
Key Coverage
- Generative AI demand
- Agentic AI
- Inference growth
- Power constraints
- Compute utilization
- Memory bottlenecks
- Software-hardware co-design
- Supply-chain concentration
Pricing Analysis
Why Cost per Token Now Matters More Than Chip Price
AI chip pricing varies widely by architecture and deployment. Frontier data-center accelerators can cost thousands to tens of thousands of dollars per accelerator-equivalent system component, while edge NPUs inside consumer SoCs add far less silicon value per device.
The better yardsticks are cost per inference or token, performance per dollar, and performance per watt. Custom accelerators gain ground where workload scale justifies specialization, while premium GPUs keep their value through software ecosystems, flexibility, and wide workload support.
The report benchmarks ASPs, system cost, wafer economics, packaging cost, memory needs, gross margins, cloud pricing, and total cost of ownership.
Key Coverage
- Accelerator ASPs
- Edge AI chip ASPs
- Cost per token
- Performance per dollar
- Performance per watt
- Manufacturing cost
- Packaging and HBM exposure
- Pricing outlook
Demand-Supply Analysis
Can Manufacturing, Packaging, and Memory Keep Up with AI Demand?
Wafer capacity is no longer the sole constraint on AI chip supply. Advanced process nodes, packaging, high-bandwidth memory, interconnect technology, and testing capacity can all constrain accelerator supply.
Leading-edge AI silicon requires cutting-edge process technology. 3-nanometer generated 24% of one leading-edge foundry's wafer revenue in 2026, while 2-nanometer hit high-volume manufacturing in late 2026.
The report maps AI chip demand against wafer starts, advanced-node capacity, packaging availability, HBM allocation, utilization, lead times, and announced expansions to identify where AI demand may encounter supply constraints through 2035.
Key Coverage
- Wafer capacity
- Advanced-node utilization
- Advanced packaging
- HBM constraints
- Accelerator shipments
- Lead times
- Capacity additions
- Regional supply dependence
Value Chain & Supply Chain
Where Value Sits Across the AI Chip Supply Chain
The AI chip value chain runs from architecture and IP through EDA, wafer fabrication, advanced packaging, memory integration, testing, board assembly, networking, and software.
The biggest value pools sit where chip architecture meets the software ecosystem, with advanced packaging and HBM acting as critical enabling layers. The report measures how architecture, fabrication, packaging, memory, networking, and software each contribute to accelerator economics.
Key Coverage
- Architecture/IP
- EDA
- Foundry
- Packaging
- HBM integration
- Board manufacturing
- Networking
- Software stack
- Margin pools and bottlenecks
Trade & Import–Export Analysis
Geographic Concentration Leaves AI Chip Supply Chains Exposed
The production of AI chips is concentrated in a limited number of areas in terms of design, manufacturing, packaging, and memory. Trade restrictions, localization policies, and subsidies for semiconductors have also influenced the supply chains of different firms.
The article analyzes trade flows, restrictions on the export of advanced chips, localization incentives, and the exposure of different manufacturing processes to geopolitical tensions. The countries discussed in the article include the United States, Taiwan, South Korea, China, Japan, Southeast Asia, Europe, and India.
Key Coverage
- AI-chip trade value
- Import/export dependence
- Advanced-chip restrictions
- Localization
- Tariffs and duties
- Regional manufacturing exposure
- Import-substitution opportunities
Technology & Innovation
Which AI Chip Technologies Will Reshape Compute Economics as Inference Grows?
AI chip innovation is moving past plain GPU scaling toward mixed architectures that combine specialized compute, high-bandwidth memory, advanced packaging, and fast interconnects. Chiplets, HBM4, low-precision arithmetic, sparse computation, and 3D hybrid bonding are reshaping the stack. UCIe has become the de facto open standard for die-to-die communication, and HBM4 has entered mass production at bandwidths above 1.65 TB/s per stack. AI economics now rest on throughput per watt, memory bandwidth, and system utilization more than peak compute. Separate designs for training and inference show that workload specialization is paying off as inference volumes grow.
The biggest shift is from maximizing general accelerator performance toward tuning whole AI systems for specific workloads. Training still depends on large accelerator clusters, but inference needs low latency, power efficiency, quick memory access, and low cost per token. That opens the door for custom ASICs, inference accelerators, and heterogeneous platforms that beat general-purpose chips on narrow workloads. Differentiation will rest on the mix of silicon architecture, HBM capacity and bandwidth, interconnect efficiency, software optimization, and workload-specific performance, not processor specs alone.
Advanced packaging and memory could end up as important as the compute architecture itself, and the industry is already moving that way. Co-packaged optics is emerging as a way to scale bandwidth while holding down power and cost. TSMC is integrating its CoWoS technology into CoWoS, and hyperscalers are pushing CPO adoption to cut networking power in AI data centers. As accelerators get faster, memory bandwidth and data movement become the main constraints, and denser clusters need faster interconnects and better packaging. This raises the importance of chiplet designs, 3D hybrid bonding, HBM, high-speed fabrics, and hardware-software co-design. The full report benchmarks these technologies across architecture, process node, HBM generation, memory bandwidth, interconnect, precision, power efficiency, packaging, R&D intensity, roadmaps, and commercial deployment, to show which are moving from development into volume production.
The report also offers a structured AI chip technology and product database covering company, accelerator, architecture, generation, process node, HBM configuration, memory bandwidth, interconnect, precision support, power, target workload, training, or inference focus, launch year, and commercial status. Users can filter by generation, workload, architecture, and application to compare roadmaps and spot where newer architectures could challenge established platforms.
Key Coverage
- GPU architecture
- Custom ASICs
- NPUs
- Chiplets
- Advanced packaging
- HBM
- Interconnect
- Low-precision computing
- Inference acceleration
- AI hardware-software co-design
- Regulation & Sustainability
Export Controls and Power Limits Now Shape Competition
Regulation now influences market access, product design, and where chips can be sold. Export controls on advanced computing can affect what products are available in a market, and localization policies encourage domestic manufacturing and packaging investment.
Sustainability is becoming a matter of performance per watt, because of the rising electricity and cooling needs of AI data centers. The report covers export-control exposure, regulatory limits, semiconductor incentives, energy use, cooling needs, and carbon impact.
Customer & Application Analysis
Hyperscalers Anchor Demand While AI Spreads to Every Compute Layer
Hyperscalers and large AI infrastructure operators hold the biggest share of data-center AI chip demand, but enterprise AI, sovereign AI programs, and edge applications are widening the customer base.
Applications include LLM training, inference, search, recommendation, generative media, agentic AI, autonomous driving, robotics, industrial automation, smartphones, PCs, and edge devices. The analysis sizes compute intensity, accelerator needs, buying criteria, qualification cycles, and switching barriers for each.
Competitive Landscape
How Do Scale, Software, and Custom Silicon Decide Control of AI Compute?
The high end of the AI-chip market is unusually concentrated, but competition is spreading as hyperscalers build custom silicon and alternative vendors target specific workloads.
NVIDIA generated USD 193.7 billion in data-center revenue in fiscal 2026, up 68% year over year, which shows how much AI value sits with one company. AMD brought in USD 16.6 billion of data-center revenue in 2026, up 32%, partly on AI accelerators.
Custom silicon is also gaining weight in the market. Amazon Web Services built its own accelerator, Trainium. Trainium2 was positioned at roughly 30 to 40% better price-performance than comparable GPU-based instances, and Trainium3 improved performance and efficiency further. Alibaba Cloud has gone down a similar path at a larger scale, with its new Zhenwu V900 designed for clusters of up to 500,000 accelerator cards.
So, the analysis looks beyond chip revenue to the software ecosystem, accelerator deployment, hyperscaler penetration, product cadence, interconnect, memory architecture, manufacturing access, power efficiency, and customer lock-in.
Tentative Leading Company Universe
| Company | Headquarters | Market Position | Core Strength | Major Applications / Segments |
| NVIDIA | U.S. | Global accelerator leader | GPU + software ecosystem | Data center, inference, training |
| AMD | U.S. | Major accelerator challenger | GPU, CPU, networking | Data center AI |
| Broadcom | U.S. | Custom AI silicon leader | ASIC and networking | Hyperscaler AI |
| Intel | U.S. | CPU/accelerator incumbent | CPUs, accelerators | Enterprise/data center |
| U.S. | Custom silicon leader | TPU architecture | Cloud AI | |
| Amazon | U.S. | Custom accelerator player | Trainium/Inferentia | Cloud AI |
| Microsoft | U.S. | Custom silicon entrant | Maia accelerators | Cloud AI |
| Qualcomm | U.S. | Edge AI leader | NPU/SoC | Smartphones, PCs, edge |
| Apple | U.S. | Integrated AI silicon leader | Neural engines/SoCs | Devices |
| MediaTek | Taiwan | Edge AI specialist | AI SoCs | Smartphones, edge |
| Samsung Electronics | South Korea | AI semiconductor major | SoCs, memory integration | Mobile, edge |
| Huawei | China | Domestic AI accelerator leader | Ascend ecosystem | Data center, AI |
| Marvell | U.S. | Custom silicon specialist | ASICs/interconnect | Data center |
| Arm | U.K. | CPU/IP architecture leader | Compute IP | Cloud, edge |
| Cerebras Systems | U.S. | AI accelerator specialist | Wafer-scale computing | Training/inference |
| Groq | U.S. | Inference specialist | Low-latency accelerators | Inference |
| SambaNova Systems | U.S. | AI accelerator specialist | Dataflow architecture | Enterprise AI |
| Tenstorrent | Canada | Emerging AI compute challenger | AI processors/IP | Data center, edge |
| Hailo | Israel | Edge AI specialist | Edge accelerators | Automotive, industrial |
| Ambarella | U.S. | Edge AI specialist | AI vision processors | Automotive, cameras |
| Horizon Robotics | China | Automotive AI specialist | Edge/vehicle processors | ADAS/autonomous driving |
| Cambricon | China | AI accelerator specialist | AI processors | Data center/edge |
| Biren Technology | China | AI accelerator challenger | Data-center GPUs | AI computing |
| Samsung Foundry | South Korea | Manufacturing enabler | Advanced logic | AI-chip production |
| TSMC | Taiwan | Foundry leader | Advanced-node manufacturing | AI accelerators |
Market Share & Competitive Ranking
How Concentrated is AI Chip Revenue at the Accelerator Level?
Share is highly concentrated in high-performance data-center accelerators, while edge AI is far more fragmented. Set NVIDIA's USD 193.7 billion in fiscal 2026 data-center revenue against AMD's USD 16.6 billion in fiscal 2026, and the gap between the leader and the nearest competitor is plain. The two figures cover different fiscal periods, so treat the comparison as a rough guide.
The full analysis splits share by data-center accelerator, custom ASIC, edge AI processor, and integrated AI SoC, so companies with very different exposure are not compared on total corporate revenue alone.
Key Coverage
- Top 5 and Top 10 share
- Accelerator revenue
- Estimated AI-chip revenue
- Share gain/loss
- Market concentration
- Data-center share
- Edge share
- Regional competitive share
Competitive Benchmarking
Why Hardware Specs Alone Don't Decide Who Wins
Companies are benchmarked on revenue growth, AI chip exposure, product breadth, architecture, software, performance per watt, memory bandwidth, interconnect, manufacturing access, customer concentration, geographic reach, and R&D.
Hardware specifications alone do not set competitive position. A technically strong accelerator can still struggle to win customers if software portability, developer tools, model optimization, or customer qualification are weak.
Product Portfolio Benchmarking
Broad Platforms or Focused Accelerators, Who Has the Edge?
The assessment maps portfolios across data-center GPUs, AI CPUs, custom ASICs, NPUs, automotive processors, edge accelerators, and integrated SoCs. It separates companies with broad platforms from specialists focused on inference or edge AI, and from newer challengers going after specific workload gaps.
Amazon's Trainium shows how the two approaches differ. AWS built it for its own cloud rather than for the open market, and Trainium2 was positioned at roughly 30 to 40% better price-performance than comparable GPU-based instances. A broad GPU platform wins on flexibility, software ecosystem, and support for almost any workload. A focused accelerator like Trainium wins where the workload is large and predictable enough to justify tuning the silicon for it. The edge goes to whichever approach fits the customer's workload mix, scale, and software commitments, so the report compares portfolios on these terms and not on chip specifications alone.
Technology & Innovation Benchmarking
Compute Density is Rising as Architectures Get More Specialized
Technology benchmarking compares processor generations, process nodes, HBM integration, interconnect bandwidth, chiplet adoption, packaging, precision formats, power efficiency, and software maturity.
Today's top designs use entire clusters instead of just single chips. For example, large TPU systems bring together thousands of chips, high-speed memory, and advanced interconnects, all working as one powerful computing system. This approach boosts performance and efficiency, allowing more complex tasks to be handled smoothly.
Application Competitive Benchmarking
Inference Taking Over from Training as the Main Battleground?
Competitive position is assessed across LLM training, inference, recommendation, generative media, enterprise AI, autonomous driving, robotics, industrial vision, and consumer devices.
The analysis identifies which vendors cover a wide range of workloads and which are tuned for a specific latency, throughput, or power limit.
Geographic Competitive Landscape
U.S. Design Leadership Meets Asian Manufacturing Scale
The competitive map covers U.S. chip designers, Taiwan-based manufacturing, South Korean memory and semiconductor strengths, Chinese domestic accelerators, and newer specialists in Europe, israel, and Canada. Each region is benchmarked on revenue, manufacturing, research and development, customer concentration, and localization.
Manufacturing & Capacity Benchmarking
Advanced Nodes and Packaging are Now Competitive Assets
AI chip competitiveness depends on access to leading-edge fabrication and advanced packaging. The report benchmarks process-node exposure, wafer access, packaging capacity, production ramps, and the geographic concentration of manufacturing.
The move to 2-nanometer production, along with continued growth in advanced nodes, matters because future accelerators need gains in both compute density and energy efficiency.
Customer & Channel Benchmarking
How Much Do Hyperscaler Relationships Decide Accelerator Scale?
The analysis compares direct hyperscaler relationships, cloud availability, OEM channels, enterprise distribution, developer adoption, software compatibility, and customer concentration.
Qualification cycles and switching costs matter a great deal, because adopting an accelerator means migrating software, tuning models, and redesigning infrastructure, not just swapping hardware.
Strategic Developments
Custom Silicon and Rack-Scale Systems are the Next Frontier
Recent activity points toward complete AI infrastructure. Major vendors are moving from standalone processors into CPUs, GPUs, networking, rack-scale systems, and software.
NVIDIA shows the direction. Its fiscal 2026 Data Center Networking revenue grew 142% to USD 31.4 billion, a sign that AI value is spreading beyond compute silicon into networking and the wider accelerated-computing platform.
M&A Landscape
What are Buyers Really Acquiring in AI Chip Deals?
AI chip M&A is focused on buying differentiated architecture, networking, systems expertise, software capabilities, and customer access.
The report reviews deals involving accelerator designers, networking businesses, system companies, and AI infrastructure specialists, with deal value, strategic rationale, technology acquired, and geographic impact where disclosed.
Company Profiles
- In-Depth Profiles of 25 AI Chip Companies
- Detailed profiles cover the same 25-company universe. Each profile follows the points below.
- Corporate and business overview
- AI-chip revenue exposure
- Product portfolio
- Accelerator architecture
- AI CPU/NPU exposure
- Revenue and growth
- R&D and capital expenditure
- Manufacturing and foundry relationships
- Advanced-node exposure
- Customer segments
- Geographic footprint
- Software ecosystem
- Partnerships
- M&A
- Product roadmaps
- Competitive strengths and vulnerabilities
Company Strategic Positioning
Different Companies Win Through Scale, Software, or Specialization
Companies are positioned qualitatively as Market Leaders, Growth Leaders, Technology Leaders, Scale Leaders, Regional Leaders, Application Specialists, and Emerging Challengers.
The assessment relies on observable attributes rather than a proprietary score, including platform scale, product cadence, ecosystem depth, manufacturing access, hyperscaler relationships, and exposure to emerging inference workloads.
Opportunity & White-Space Analysis
Where Do New AI Chip Value Pools Appear Beyond Training GPUs?
The biggest white spaces are forming around the areas below.
- Inference-optimized accelerators
- Agentic AI
- Sovereign AI infrastructure
- Energy-efficient compute
- Automotive AI
- Robotics
- Industrial edge AI
- Custom hyperscaler silicon
- AI PCs and smartphones
- Specialized scientific computing
- Low-latency inference
- Emerging-market AI infrastructure
The report sizes each one by revenue pool, CAGR, penetration gap, regional demand, and required investment
Industry Structure
High Entry Barriers Sit Alongside Fast Architectural Change
Supplier power is high. Advanced-node fabrication, packaging, and memory access sit with a small number of suppliers.
Buyer power is medium to high. Hyperscalers buy at huge scale and increasingly design their own silicon.
The threat of new entrants is medium. New architectures are possible, but software ecosystems, capital needs, and manufacturing access make entry hard.
The threat of substitutes is medium. CPUs, GPUs, ASICs, and NPUs compete on workload economics, with no single winner.
Competitive rivalry is high. Fast product cycles, custom silicon, and workload specialization keep the pressure on.
PESTLE Analysis
How Chip Policy and AI Infrastructure Spending Feed Each Other
The analysis looks at semiconductor subsidies, export controls, national AI strategies, economic cycles, energy availability, workforce needs, technology change, intellectual-property rules, and environmental limits. It pays special attention to how AI infrastructure investment and semiconductor localization influence one another.
Market Attractiveness
Where Compute Demand and Specialization Overlap, Growth is Highest
Attractiveness is assessed on growth, market size, margins, entry barriers, technology intensity, customer concentration, capital needs, and supply-chain access.
The analysis separates high-growth but capital-heavy data-center accelerators from lower-ASP, higher-volume edge AI markets, so the market is not treated as one uniform opportunity.
Future Outlook
Will Inference, Agentic AI, and Physical AI Reshape 2035 Profits?
By 2035, AI chip competition is likely to center on inference economics, agentic workloads, power efficiency, custom silicon, and system-level integration rather than training performance alone.
The base case assumes high-20% market growth through 2030. The upside case adds faster agentic AI adoption, sovereign AI infrastructure, and physical AI deployment. The downside case reflects slower AI monetization, hyperscaler capex slowing down, a semiconductor-cycle correction, export restrictions, and slower edge adoption.
The AI chip market is evolving from a processor market into an integrated compute-platform market. Companies that combine silicon, memory, networking, packaging, and software should capture more of the growing value pool, while specialists can build strong positions by focusing on inference, edge AI, automotive workloads, or power-constrained uses.
Artificial Intelligence (AI) Chip Market Segments
By Chip Type
- GPU
- CPU
- ASIC
- FPGA
- NPU
- AI Accelerator
- Other AI Chips
By Computing Type
- Training
- Inference
- Training and Inference
By Architecture
- Monolithic
- Chiplet-Based
- Heterogeneous
- 3D-Integrated
By Processing Type
- Central Processing
- Parallel Processing
- Tensor Processing
- Neuromorphic Processing
By Technology
- Conventional Computing
- Low-Precision Computing
- Sparse Computing
- High-Bandwidth Memory
- Advanced Packaging
- High-Speed Interconnect
- 3D Integration
By Memory
- HBM
- GDDR
- DDR
- SRAM
- Other Memory Technologies
By Process Node
- Below 7 nm
- 7–16 nm
- Above 16 nm
By Application
- Generative AI
- Machine Learning
- Computer Vision
- Natural Language Processing
- Autonomous Systems
- Robotics
- Recommendation Systems
- Speech Recognition
- Other AI Applications
By End Use
- Data Centers
- Cloud Computing
- Enterprise Computing
- Consumer Electronics
- Automotive
- Robotics
- Healthcare
- Telecommunications
- Industrial
- Defense and Aerospace
- Other End Uses
By Deployment
- Cloud
- On-Premises
- Edge
By Data Center
- Hyperscale Data Centers
- Colocation Data Centers
- Enterprise Data Centers
By Region
- North America
- U.S.
- Canada
- Europe
- Germany
- UK
- France
- Netherlands
- Asia Pacific
- China
- Japan
- South Korea
- Taiwan
- India
- Singapore
- Australia
- Latin America
- Brazil
- Mexico
- Middle East & Africa
For inquiries regarding discounts, bulk purchases, or customization requests, please contact us at sales@precedenceresearch.com
Frequently Asked Questions


Ask For Sample
No cookie-cutter, only authentic analysis – take the 1st step to become a Precedence Research client
 Get a Sample
 sales@precedenceresearch.com
 Schedule a Meeting